No Model in Amazon's Sofa Benchmark Could Reliably Check an AI Edit
Amazon researchers' V-CAPE benchmark asked vision-language models whether AI-edited product photos kept the product intact. With a plain prompt the best scored 63.5% across both subsets, where approving everything earns about half. Photoroom sells an automated fidelity gate for fashion but graded its own benchmark with people, and Etsy's rules leave the final check to buyers.
Neritus Vale
Researchers at Amazon have tested whether AI can check an AI-edited product photo, and the results leave the job with people. Their benchmark, V-CAPE, posted on 28 October, asks models whether a product survived its edit. Across its two subsets, the best model tested scored 63.5% with a plain prompt, closer to a coin toss than to an inspector. Etsy and Vestiaire Collective now let AI rework listing photos; Etsy leaves bad edits to seller liability, and Vestiaire relies on its vendor’s fidelity claim.
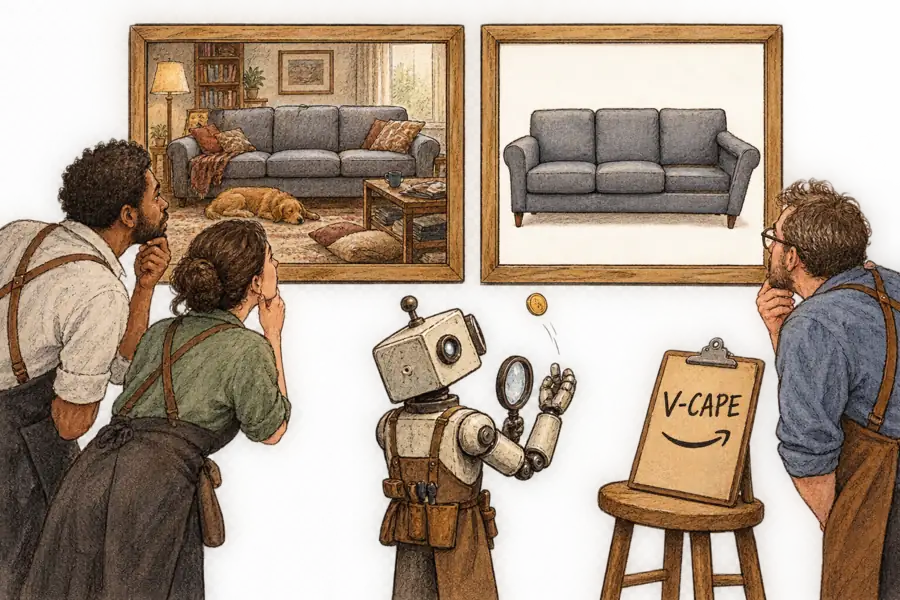
Nothing in the benchmark is worn. Its real subset holds 20,000 pairs built from sofa photos in public e-commerce listings, each set on white by a Gemini model and, where needed, turned to face left by a second one (section 3.1, appendix A.1). A synthetic subset of the same size renders chairs, tables, lamps and pillows. The authors stress that their pipeline “does not reflect any production system”.
The edit resembles the one resale fashion now buys, but it does more. On every new Vestiaire listing, Photoroom’s API “removes the background from the main photo, adds a shadow, centers the item and corrects the lighting”, Photoroom says. V-CAPE’s prompt asks for a “PURE WHITE background” with “light shadows”, but it also strips the original lighting and removes people, pets and decor.
People wrote the answer key. Three trained annotators judged each pair, the majority decided, and their agreement reached a Fleiss’ kappa of 0.77 after five alignment rounds (section 3.3).
The real subset is balanced so that approving every edit earns half marks. Several models came close to answering every pair the same way, what the paper calls “near-universal rejection or acceptance” (section 4.1).
Neither size nor prompting rescued the models. The roster ran from open Qwen3, Gemma and Mistral models to Anthropic’s Claude and Amazon’s own Nova; no GPT or Gemini model was tested as a judge. The authors report that an automatically tuned prompt added three to five points, though that prompt tells the model its ground-truth labels are correct, which may flatter the gain. They conclude that the bottleneck lies “not only in instruction design, but in the underlying perceptual capabilities”.
On the real sofas, fine-tuning did even less. The authors tuned a small Qwen model on 55 examples, 35 of them real (Table 1). Accuracy stayed near 52%. Its F1 score leapt, the signature of a model that swapped rejecting everything for approving everything.
The paper’s premise and conclusion pull against each other. Its abstract calls manual inspection “infeasible” at scale. Its societal-impact appendix says the results suggest “human oversight will remain essential for the foreseeable future”. Every marketplace that lets AI edit photos sits between those two sentences.
Photoroom’s fidelity benchmark was graded the way Amazon’s was, by people. It ran clothing, footwear, bags, jewellery and accessories through four image-editing models for virtual model generation, a different task from V-CAPE’s clean-up, and asked of every output: “is this still the same product?” At least three trained annotators reviewed each image, and one flag meant failure. That bar is stricter than V-CAPE’s majority vote. The best model passed 29.0% of the time.
Neither benchmark let a machine write its answer key.
The check Photoroom sells is a machine. In a proof of concept, AI ironing ran with its Fashion Fidelity Rater as the gate. The system “processed over 2 million garment images for a fashion marketplace and sent only seven to human review, meeting the brand’s fidelity criteria”, the vendor writes.
Seven in two million is the count a near-perfect rater would produce. A rater that passes nearly everything would produce the same handful, and V-CAPE found general models with that habit. Telling them apart takes a human audit of what passed. Photoroom’s other figures, 99.9% of checks cleared without review in a live resale deployment and no negative effect on return rates in a six-week trial, do not test whether the rater agrees with a person.
Etsy’s stated aim is buyer trust, but the one unedited photo most listings now need also hands a buyer a before picture to hold the AI-edited images against, and those images must not “make the item appear different”. At upload Etsy detects AI-generated images and offers tips, and says that “over time, we plan to more proactively enforce these requirements as listings are created”. It does not say those checks compare an edit with its source photo. If a buyer’s case shows an item “materially different from your listing”, the seller “may be responsible for refunding the buyer”.
If the paper’s pattern holds outside furniture, clothing is the harder case. Six in ten rejected sofa edits failed on geometry (Table A.1), a fault the authors class as coarse. Detection of finer faults in texture, colour or material stays “close to chance across the board”, they report. Photoroom’s QA guide makes the vendor’s own claim: “Fashion images present more fidelity risk per pixel than most product categories.”
The strongest objection is that no marketplace would check photos with a general model and a prompt. Photoroom’s raters are category-specific models, “available today for food and fashion”, and persistent failures reach a person “with a confidence score”. V-CAPE’s one tuned model saw 55 examples. For the thesis to fail, a purpose-built rater must agree with trained reviewers as often as they agree with each other, and know when it is unsure.
Photoroom’s posts report no such test, and its guide still calls human review “the exception path, not the default”. At full strength, the objection moves people to the end of the line, where they still decide.
The review does not disappear when a machine cannot do it; it moves. A marketplace can pay people to compare pictures before a listing goes live. Or it can let buyers compare the parcel with the photo, as Etsy’s rules do today. If the machines stay where V-CAPE found them, the cheapest reviewer is the customer, and the seller’s bill arrives as a refund.