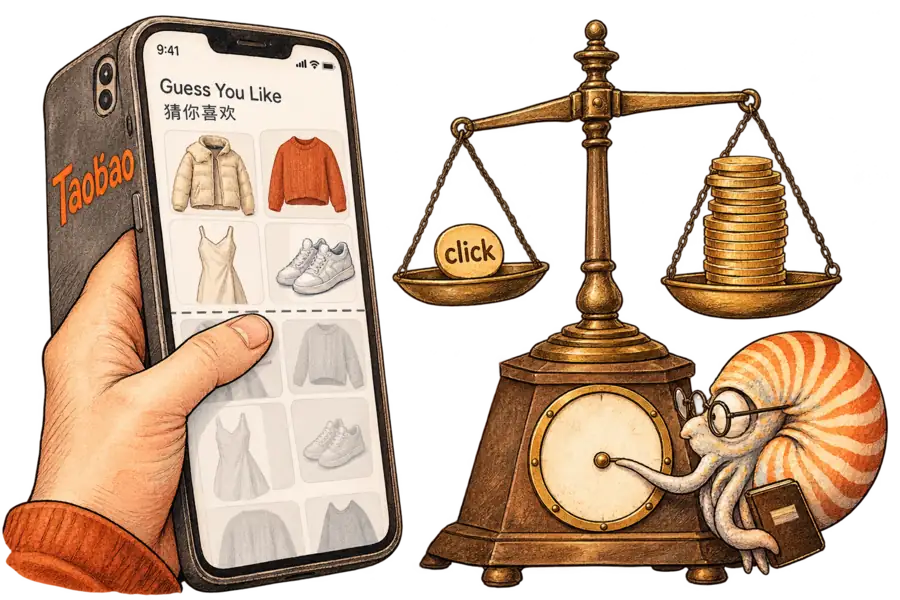
Whose Revenue Rose 3.67% When Taobao Learned Where Shoppers Stop Scrolling?
Taobao's Guess You Like feed now picks each list with an evaluator that predicts how far a shopper will scroll. In a live test clicks rose 0.70% and "commercial revenue" 3.67%, but the paper never defines that revenue, never says which weight production uses and prints no order, GMV or advertiser figure, so it cannot show whether shoppers or the platform gained.
Neritus Vale
Taobao’s Guess You Like feed now chooses each list it shows with a model that predicts how far the shopper will scroll before stopping. In a live test, the change lifted clicks by 0.70% and “commercial revenue” by 3.67%. The paper never says what that revenue is, so it cannot show whether the gain went to shoppers or to the platform.
The change sits in the evaluator, the last step before the screen. A generator proposes candidate orderings and the evaluator picks one to display. Authors from Alibaba’s Taobao & Tmall Group and Xi’an Jiaotong University posted the paper this week. Most existing evaluators, they argue, reduce a list to “independent per-item predictions” such as click-through rate. That ignores two “physical realities”: a click needs the item to be reached and seen, and items “compete for finite user attention”.
The new Impression-Click Evaluator, ICE, models the chain from display to impression to click. It predicts a distribution of browsing depth, the last position a shopper reaches, and derives from it the chance that each slot is seen. A training objective makes predicted clicks share “a finite probability budget” across the list, so one item’s pull lowers its neighbours’.
The paper’s logs show the size of the first problem. In the week of industrial data it trains and tests on, users saw about 58% of the items displayed to them, by our arithmetic. An evaluator that treats every slot as seen credits the rest with value they never deliver, a flaw the authors call “systematic tail-utility overestimation”.
The second problem has a clothing case, though the paper never mentions clothing; the case is ours. Once a shopper clicks an item and is satisfied, the paper says, “the marginal utility of subsequent similar items drops significantly even if their individual quality is high”. Picture the near-twin of a jacket already clicked, waiting further down the same list.
The first problem is old news in web search. In 2008, Microsoft researchers found that a “cascade” model best explained click bias near the top of results pages. In it, “users view results from top to bottom and leave as soon as they see a worthwhile document”. ICE carries the top-to-bottom part into the stage that picks whole lists.
The paper’s offline tests measure impressions and clicks, never money. Its list-level measure, SeqAUC, treats the observed total clicks in each list as the ground truth, and ICE improved it on all six backbones tested.
The live test ran in the Guess You Like feed of the Taobao App, which the paper calls “a flagship recommendation scenario”. Impressions, the items shoppers saw, rose 0.58%. The paper does not say whether that came from deeper scrolling or from more visits. Clicks rose 0.70%, close to the impression figure.
Revenue did not keep step. It rose about five times as much as clicks. If revenue scales with clicks, most of the gain came from what each click was worth, not from more clicking. By our arithmetic on the paper’s figures, each click would then have brought in about 3% more than in the control group.
The worth the evaluator assigns each item is a setting. Its scoring formula multiplies each slot’s chance of being seen and clicked by a weight. Equal weights count clicks, while the “predicted purchase value or bid price” targets “expected GMV or ad revenue”. The paper never says which weight production uses. Its results report a third term, “commercial revenue”, that matches neither label.
Both settings map onto how Alibaba earns. Its latest annual report says Taobao and Tmall merchants can buy “in-feed marketing”. Its customer management revenue is charged mainly per click, per thousand impressions, by time and per sale. The two events ICE predicts are thus two of the units Alibaba bills for. The paper does not say whether the lists ICE scores include paid items.
A model that knows where scrolling stops can also tell which slots are worth selling.
Nothing in the paper separates the readings. It reports no orders, no GMV, no purchase conversion rate and no figure for sellers or advertisers. The test ran on 5% of traffic and reports no confidence interval.
The paper’s only long-run measure of shoppers is a guardrail. A “14-day Lifetime Value” gauge, kept “to monitor user retention”, rose 0.23%, which the authors read as gains “sustained without compromising the long-term user experience”. The paper does not define the gauge. Whatever it counts, it cannot show what the lists sold shoppers, or who was paid.
The paper’s best case is that shoppers gained too: they saw more, clicked more and scored slightly higher on the retention guardrail. If production weights items by predicted purchase value, a sharper evaluator moves likely purchases into the slots people see. For that case to hold, the revenue figure would have to measure sales, and the extra sales would have to be things shoppers wanted rather than dearer substitutes.
The authors know how to print a sharper figure. Han Zhu and Jian Xu, two of ICE’s authors, co-wrote BAR, a 2025 study of Alibaba’s display advertising. There, click-through rate “serves to evaluate user experience” and return on investment “is employed to measure the advertiser’s experience”. ICE reports clicks, impressions and “commercial revenue”, with no ROI-type advertiser figure. Beyond clicks and the retention guardrail, it reports no shopper outcome. On the evidence printed, the shopper’s share of the gain is an assumption.
The paper pitches ICE as “plug-and-play”. If other shopping feeds plug it in, they will value the slots shoppers reach more highly and discount the rest. The weight behind those choices then matters more, and it is the number ICE omits. ByteDance’s slate-ranking paper kept its own production setting private too, though it printed GMV per user and advertiser value.
For a clothing label in that feed, every slot would be discounted by its chance of being seen. If production weights by bid price or purchase value, a weight the label cannot see helps decide who gets the slots that count. Printing that weight would cost Taobao a sentence. Without it, the gain has no owner on paper.