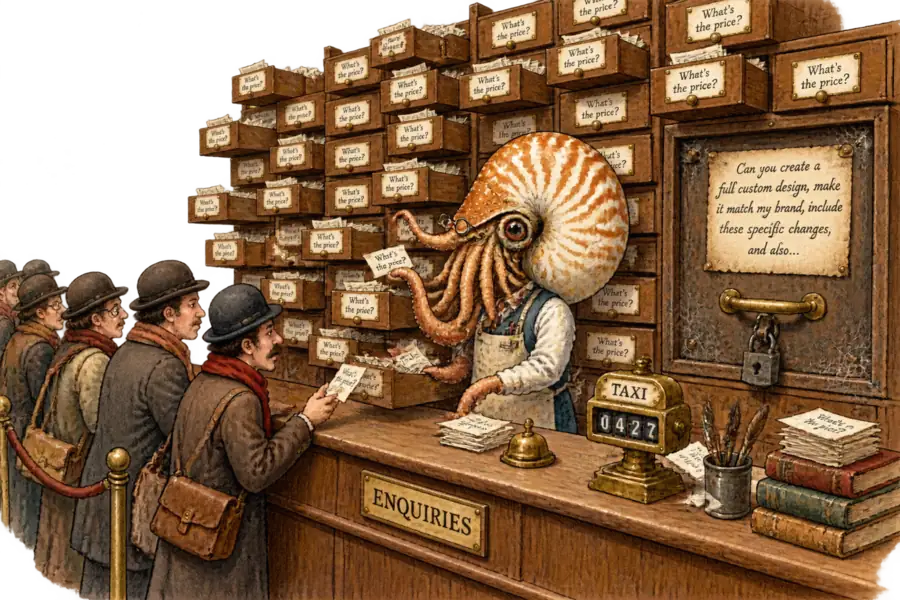
The Cache Decides Which Questions a Retail Assistant Can Afford
Prompt caching only pays for itself when the same question comes back, and a semantic-caching paper illustrates repeat-heavy query categories at 40 to 60 percent hit rates against 5 to 15 percent for sparse ones. That arithmetic makes catalogue questions cheap and makes the bespoke styling every vendor demos the most expensive thing an assistant can be asked to do.
Neritus Vale
Every retail AI assistant is priced on a bet that customers repeat themselves. Reading a cached prompt costs a tenth of the normal input rate on Anthropic’s published pricing. Writing that cache costs 25 percent more than not caching at all, for the standard five-minute cache; the one-hour option costs double. The discount is a loan that clears only when the same prompt comes back, and twice over if the cache is running on the longer clock. Conversational shopping is moving out of pilot and into production traffic on that assumption. It holds far better for questions about the catalogue than for questions about the customer.
Repetition rates vary enormously with what kind of question is being asked. A 2025 position paper on category-aware semantic caching illustrates the arithmetic with a representative production workload: 40 to 60 percent hit rates for query categories that repeat heavily. That is the top of the range the paper uses to make its case, not a figure it reports having measured. Sparse or volatile categories sit at the bottom, 5 to 15 percent, which is the gap between a cache that pays for the infrastructure around it and one that does not. Its material was code and conversation rather than shopping, so the analogy has to be drawn rather than assumed. The property doing the work transfers cleanly: templated questions cluster and recur, open-ended ones scatter.
Below a certain hit rate, caching a question costs more than answering it cold. The same illustrative workload puts the break-even for a conventional vector-database cache at a 15 to 20 percent hit rate, because the lookup runs on every miss and has to be paid for out of the hits. Below that line, the infrastructure is a cost centre dressed as a discount. By the paper’s own framing, that leaves 20 to 30 percent of production traffic excluded from the cache by design. The excluded questions are not unimportant. They are unrepeated, and unrepeated is the one property no discount can price.
A cache does not reward a good question; it rewards the same question.
Amazon built the routing this arithmetic implies and then described it in public. Its engineers, writing about how Rufus was served, split the traffic in two: “what is the wattage on this drill?” goes to smaller, faster models, while planning a camping trip or choosing a gift earns deeper reasoning and multi-turn dialogue. Prompt caching appears in the same passage as parallel tool calling, filed under latency. The assistant itself was folded into Alexa in May, as we reported at the time, but the engineering disclosure outlived the product. It is the clearest public statement of the rule: the shape of the question decides which model answers it, and therefore what the answer costs.
What counts as reuse is narrower than the word suggests. A caching framework posted to arXiv in July and revised this month converts reasoning programs into parameterised objects, on the observation that many requests “share similar computational structures while differing in variables”; it reports up to roughly a threefold latency gain on request sets that include the WebShop shopping benchmark. The unit being reused is the structure of the request, with the specifics swapped in. ASOS launched its Stylist app inside ChatGPT in May, and the example prompt in its own announcement was “show me pastel floral A-line dresses for spring”. Colour, print, silhouette, season: four slots and a lookup, a catalogue filter wearing the clothes of a styling conversation, and it caches beautifully.
The request that does not decompose into slots is the one shoppers say they want. Asos’s own survey, reported here this morning, found UK consumers asking retailers for styling guidance rather than a wider range. Guidance is unrepeatable by construction, because it is defined by the person asking for it. It is also, unsurprisingly, the question most vendor demos lead with. The impressive question and the expensive question are the same question.

The contracts written on top of this hide the variance rather than resolve it. Intercom charges $0.99 per resolved conversation and bills once however many questions the customer asks inside it. That is a flat price over a cost base that moves with which model answers and how much it writes, which makes the vendor’s margin a standing bet on query mix. Amazon could absorb that bet at the scale of three million tokens a minute during Prime Day. A mid-market retailer buying resolutions by the unit is on the other side of it.
The strongest objection is that prefix caching does not care what the customer asks. The system prompt, the tool definitions and the catalogue context sit ahead of every query, so the styling question rides the same discount as the stock check. A retailer convinced that hard questions convert better should be glad to pay more for them. For the objection to hold, the conversion premium on unrepeatable questions must scale with their cost premium at every retailer, not only at the one with the largest catalogue and an advertising business attached to the answer.
The discount stops exactly where the shared prefix stops. Anthropic’s documentation states that a cache hit requires 100 percent identical segments up to the breakpoint, and that caching has no effect on output token generation. Everything past that point is billed at full rate: the retrieved products, the customer’s stated constraints, and the whole written answer, which across Anthropic’s current model line is priced at five times the input that produced it. A bespoke styling turn is the longest answer an assistant will ever write. It is also the one part of the transaction no cache has ever touched.
None of this makes the styling conversation impossible. It makes it a line item somebody has to argue for, and priced honestly it is marketing spend rather than support automation, which puts it in a different budget with a different hurdle rate. The retailers who keep offering it will be the ones who decided to, having seen the number. The ones who stop will not announce it. If the cost line goes unargued, their assistants will simply get better and better at answering questions about the catalogue, because that is what the cache was always going to pay for.